TL;DR
- In Building AI Models Without Gradient Descent, a frontier model (Anthropic's Fable,
claude-fable-5-1) wrote every weight of a neural network from a written spec, with no training data and no optimiser. This post is looking at if that approach can actually be useful, with two jobs that have nothing in common: spotting a coding agent stuck in a loop, and lighting a cloud. - Agent loops. A 2.1M-parameter transformer that labels what an agent is doing after every tool call. 0.957 macro-F1 (sealed test) and 0.908 (sealed OOD), with 6.8% false alarms off distribution against 34.5% for the same network trained on 223,930 labels. It costs about 0.23 s of CPU per whole session, and US$64.62 to write.
- Cloud light. A 3,057-parameter network that tells a ray marcher how much light reaches each point inside a cumulus cloud. 13.8% luminance error against path-traced references (reference split) and 15.5% (held back), against 82.4% and 90.4% for single scattering. It cost US$75.77 to write. Because almost every weight is zero or a formula, it compiles into 116 lines of shader arithmetic and runs at 60 fps in the browser. You can drag the sun around below.
- The common thread: the stochastic, expensive step (a frontier model reasoning for an hour or two) happens once, under a harness that records it. What ships is a small file that rebuilds byte for byte, comes with a document that says what each part does, and needs no LLM to run. Everything here is one authoring run per job, on synthetic data or a single synthetic scene.
A Different Kind of Model
The usual ways to get a model for a narrow job are to train one on labelled examples, or to take a general-purpose model and prompt or fine-tune it. Either way the weights come out of an optimiser, and what you get to inspect is the behaviour, not the mechanism.
The previous post tested a third route. Give a frontier model a network with every weight set to zero and a written description of the job, and ask it to set the weights itself, the way you'd ask it to write a program. No training set, no gradient descent. What comes back is a builder script that sets every parameter, a weights file built from it, and a document that says what each part of the network computes.
That post asked whether this works. On one synthetic benchmark it did, and held up better off distribution than training the same network. This post asks a different question: if you can get a network this way, what is it good for?
I tried it on two jobs that share nothing except that both needed a model:
- Watching coding agents. After each tool call, decide whether the agent is making progress or stuck in a loop. This is an observability problem: a judgement on every event of a stream, where false alarms are expensive and the input distribution keeps shifting.
- Lighting a cloud. For every point inside a cumulus cloud, estimate how much sunlight, skylight and ground light arrives there after bouncing around inside it. This is a graphics problem: the exact answer takes a path tracer minutes per frame, and a game needs it in milliseconds.
Fable wrote both networks. Neither was trained.
Job One: Is the Agent Stuck?
Anyone who has run coding agents for long, especially quantized local models, has watched one get stuck: editing the same file back and forth, rerunning the same failing test, exploring without converging. The previous post built a benchmark for exactly this. After every tool call, a classifier looks at the agent's last eight operations and picks one of four labels: PRODUCTIVE, RECOVERY (a bounded retry), STALLED (repeating work already done) or OSCILLATING (undoing and redoing).
The hard part is that loops and progress can look alike on the surface. Two sessions can share the same rhythm, an edit that succeeds and then a test that fails, four times over, and one is stuck at 11 of 16 tests while the other is climbing 3, 5, 8, 11, then 14 of 14.
Show the numbers
| Session, operation | Tool and target | Status | Tests passed or file hash | Hidden effect | Label of the window ending here |
|---|---|---|---|---|---|
| Flips webhook.go between two versions, op 0 | search src | ok | none | — | |
| Flips webhook.go between two versions, op 1 | read_file internal/identity/slugify.go | ok | none | — | |
| Flips webhook.go between two versions, op 2 | edit_file internal/identity/webhook.go | ok | hb1c6547a05 > h3900d57125 | none | — |
| Flips webhook.go between two versions, op 3 | run_tests ./internal/...:unit | FAILED | 11/16 | new fact learned | — |
| Flips webhook.go between two versions, op 4 | edit_file internal/identity/webhook.go | ok | h3900d57125 > h982d5fe6e3 | none | — |
| Flips webhook.go between two versions, op 5 | run_tests ./internal/...:unit | FAILED | 11/16 | none | — |
| Flips webhook.go between two versions, op 6 | edit_file internal/identity/webhook.go | ok | h982d5fe6e3 > h3900d57125 | undoes an earlier edit | — |
| Flips webhook.go between two versions, op 7 | run_tests ./internal/...:unit | FAILED | 11/16 | none | ambiguous (not scored) |
| Flips webhook.go between two versions, op 8 | edit_file internal/identity/webhook.go | ok | h3900d57125 > h982d5fe6e3 | undoes an earlier edit | OSCILLATING |
| Flips webhook.go between two versions, op 9 | run_tests ./internal/...:unit | FAILED | 11/16 | none | OSCILLATING |
| Flips webhook.go between two versions, op 10 | edit_file internal/identity/webhook.go | ok | h982d5fe6e3 > h3900d57125 | undoes an earlier edit | OSCILLATING |
| Flips webhook.go between two versions, op 11 | run_tests ./internal/...:unit | FAILED | 11/16 | none | OSCILLATING |
| Flips webhook.go between two versions, op 12 | edit_file internal/identity/webhook.go | ok | h3900d57125 > h982d5fe6e3 | undoes an earlier edit | OSCILLATING |
| Flips webhook.go between two versions, op 13 | run_tests ./internal/...:unit | FAILED | 11/16 | none | OSCILLATING |
| Flips webhook.go between two versions, op 14 | edit_file internal/identity/webhook.go | ok | h982d5fe6e3 > h43abbdfa4c | progress (fixes something) | PRODUCTIVE |
| Flips webhook.go between two versions, op 15 | run_tests ./internal/...:unit | FAILED | 13/16 | none | PRODUCTIVE |
| Fixes something on each pass, op 0 | read_file lib/orders/scheduler.rb | ok | none | — | |
| Fixes something on each pass, op 1 | read_file lib/orders/migrations.rb | ok | none | — | |
| Fixes something on each pass, op 2 | search docs | ok | none | — | |
| Fixes something on each pass, op 3 | list_dir . | ok | none | — | |
| Fixes something on each pass, op 4 | read_file spec/orders/migrations_request_spec.rb | ok | none | — | |
| Fixes something on each pass, op 5 | list_dir spec | ok | none | — | |
| Fixes something on each pass, op 6 | edit_file lib/orders/timezone.rb | ok | h299630c5f0 > hd57cb1154a | none | — |
| Fixes something on each pass, op 7 | run_tests spec:request | FAILED | 3/14 | new fact learned | ambiguous (not scored) |
| Fixes something on each pass, op 8 | edit_file lib/orders/locale.rb | ok | h15aeac96e1 > h6061660a46 | progress (fixes something) | PRODUCTIVE |
| Fixes something on each pass, op 9 | run_tests spec:request | FAILED | 5/14 | new fact learned | PRODUCTIVE |
| Fixes something on each pass, op 10 | edit_file lib/orders/notifier.rb | ok | h614ce37a11 > h8fcbc4e82c | progress (fixes something) | PRODUCTIVE |
| Fixes something on each pass, op 11 | run_tests spec:request | FAILED | 8/14 | new fact learned | PRODUCTIVE |
| Fixes something on each pass, op 12 | edit_file lib/orders/notifier.rb | ok | h8bfc68a6d0 > h7c4a473a46 | progress (fixes something) | PRODUCTIVE |
| Fixes something on each pass, op 13 | run_tests spec:request | FAILED | 11/14 | new fact learned | PRODUCTIVE |
| Fixes something on each pass, op 14 | edit_file lib/orders/timezone.rb | ok | hd57cb1154a > h0413cb5346 | progress (fixes something) | PRODUCTIVE |
| Fixes something on each pass, op 15 | run_tests spec:request | ok | 14/14 | none | PRODUCTIVE |
| Fixes something on each pass, op 16 | run_tests spec:feature | ok | 7/7 | none | PRODUCTIVE |
| Retries the same failing suite, op 0 | search src | ok | new fact learned | — | |
| Retries the same failing suite, op 1 | read_file src/cli/rateLimiter.ts | ok | new fact learned | — | |
| Retries the same failing suite, op 2 | plan | ok | none | — | |
| Retries the same failing suite, op 3 | list_dir tests/fixtures | ok | none | — | |
| Retries the same failing suite, op 4 | read_file src/cli/__tests__/rateLimiter.integration.test.ts | ok | none | — | |
| Retries the same failing suite, op 5 | list_dir .github/workflows | ok | none | — | |
| Retries the same failing suite, op 6 | run_tests contract | FAILED | 7/9 | none | — |
| Retries the same failing suite, op 7 | run_tests contract | FAILED | 7/9 | bounded retry | RECOVERY |
| Retries the same failing suite, op 8 | read_file src/cli/__tests__/rateLimiter.contract.test.ts | ok | none | RECOVERY | |
| Retries the same failing suite, op 9 | run_tests contract | FAILED | 7/9 | bounded retry | RECOVERY |
| Retries the same failing suite, op 10 | run_tests contract | FAILED | 7/9 | bounded retry | RECOVERY |
| Retries the same failing suite, op 11 | read_file src/cli/rateLimiter.ts | ok | repeats work already done | RECOVERY | |
| Retries the same failing suite, op 12 | run_tests contract | FAILED | 7/9 | repeats work already done | ambiguous (not scored) |
| Retries the same failing suite, op 13 | search src | ok | repeats work already done | ambiguous (not scored) | |
| Retries the same failing suite, op 14 | read_file src/cli/__tests__/rateLimiter.contract.test.ts | ok | repeats work already done | ambiguous (not scored) | |
| Retries the same failing suite, op 15 | run_tests contract | FAILED | 7/9 | repeats work already done | STALLED |
| Retries the same failing suite, op 16 | read_file src/cli/rateLimiter.ts | ok | repeats work already done | STALLED | |
| Retries the same failing suite, op 17 | run_tests contract | FAILED | 7/9 | repeats work already done | STALLED |
| Retries the same failing suite, op 18 | read_file src/cli/__tests__/rateLimiter.contract.test.ts | ok | repeats work already done | STALLED | |
| Retries the same failing suite, op 19 | run_tests contract | FAILED | 7/9 | repeats work already done | STALLED |
| Retries the same failing suite, op 20 | search src | ok | repeats work already done | STALLED | |
| Retries the same failing suite, op 21 | run_tests contract | FAILED | 7/9 | repeats work already done | STALLED |
datasets/v0_2/MANIFEST.json @ 51c9fa8 (dev split)Fable wrote a 2,128,932-parameter transformer for it from the spec alone, then revised it once after seeing 200 labelled windows. The results, every number with its split (macro-F1 runs from 0 to 1, with all four labels weighted equally; a "sealed" set was hashed before any model existed and scored once; OOD logs come from a second generator that Codex wrote independently):
| Written by Fable | Same network, trained | |
|---|---|---|
| Labels used | 200 windows | 223,930 windows |
| Macro-F1, sealed test | 0.957 | 0.923 |
| Macro-F1, sealed OOD | 0.908 | 0.488 |
| False alarms, sealed OOD | 6.8% | 34.5% |
| Cost to produce | US$64.62 of model usage | about 3.75 h on two CPU threads, plus the labels |
The scores were the point of the last post. What matters for this one is what comes out of the authoring step, and what it is like to run.
It is cheap enough to run on every event. The written network needed a median 0.23 s of CPU time to label every window in a whole session, on two threads of an Intel Mac, about 2,700 tokens per CPU-second. It is an 8.5 MB file. There is no LLM in the path, no API call per event and no GPU. That moves it from "something you sample" to "something you run on every tool call of every agent", which is what a monitor needs to be.
It rebuilds from source. The weights come from a 422-line Python builder that reruns to a byte-identical file. A change to the network is a diff to that script, reviewable like any other change, and the build is reproducible in the way a trained checkpoint usually isn't (a retrain is only bit-for-bit on the same thread count, torch build and CPU).
You can ask it why it fired. Fable documented every non-zero block of the network in a CIRCUITS.md, and each label's score maps back to a rule in that document. Alongside the network sits a plain Python version of the same policy, and the two agree on at least 99.95% of windows on every split I scored. That gives a check that needs no labels at all: run the readable policy beside the network, and if they ever disagree on live traffic, something has drifted.
Its mistakes. When the first version scored 0.744 (sealed test) with zero labels, the shortfall was in the policy Fable chose, not in how faithfully it compiled that policy into weights. That is the kind of failure an LLM can fix quickly by changing the rule, and the 200-window revision did exactly that.
It held up when the logs changed. The 34.5% false-alarm rate is the number that matters most for a monitor. A detector that flags a third of healthy agents as stuck gets switched off. The trained network learned the first generator's habits; the written one encoded a rule about repeated work, and the rule travelled.
For a product, this could be used as a component inside an agent harness: after each tool call, label the last eight operations; on STALLED or OSCILLATING, intervene (change strategy, add context, escalate to a person, or stop). The model costs a fraction of a CPU-second per session and can be diffed, rebuilt and explained and easily modified further by the author LLM.
- Productive
- Recovery
- Stalled
- Oscillating
Show the numbers
datasets/v0_2/MANIFEST.json @ 51c9fa8 (dev split; sessions s-8c4e2bce5b5ce097, s-35f046b90b6b6352, s-b85d987d455fc994)Job Two: Light Through a Cloud
The second job came from wanting to know whether any of this was specific to classifying logs. So I picked something as different as I could: rendering.
A cumulus cloud is white because light enters it and scatters dozens or hundreds of times before it leaves. Getting that right takes a path tracer, which follows millions of light paths per image and takes minutes or hours. Games and films usually cheat with a handful of tricks that get the bright top and dark base roughly right but miss the glowing edges when the sun is behind the cloud, the soft light deep inside, and the way the colour changes at sunset. In 2017 Disney Research showed a neat middle path, Deep Scattering (Kallweit et al., SIGGRAPH Asia 2017): a ray marcher steps through the cloud, and at each step a neural network looks at the density around that point and predicts how much light arrives there. Theirs was trained on path-traced data.
I asked Fable to write one instead. The setup:
- A scene. One procedurally generated cumulus cloud, about 1.5 km across and 1 km tall, its base 1.5 km above flat ground, under a physically based sky.
- A renderer. A three.js ray marcher. At each step it asks the network for three numbers: how much of the sun's light, the sky's light and the ground's light reaches this point and scatters towards the camera. The renderer multiplies those by the actual sun, sky and ground colours, so sunset colour comes from the lighting, not the network.
- What the network sees. It chooses up to 64 probes: samples of the cloud's density at chosen offsets from the point, towards the sun, up, down or along the view, blurred over a chosen width. Plus the angles between the sun, the view and the vertical.
- References. Path-traced images from Mitsuba 3 (a research path tracer) for 12 sun and camera pairs, which Fable could look at beside its own renders. Six more pairs were held back and only scored at the end.
- The rules. No fitting tool, no optimiser and no solving for constants against the references. It could write Monte Carlo simulations of its own, render its network, look at the frames and measure them.
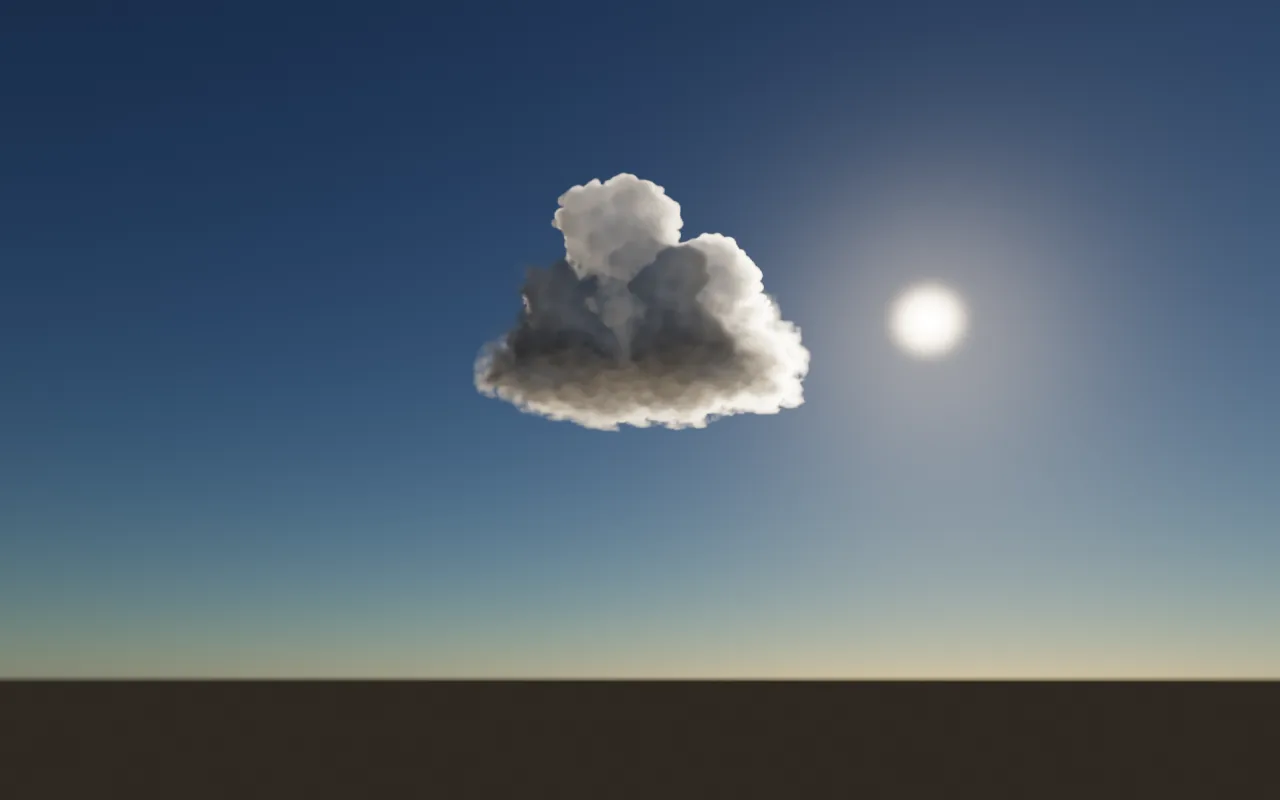
Show the numbers
| Renderer | Reference (12) | Held back (6) |
|---|---|---|
| Single scattering only (baseline) | 82.4% | 90.4% |
| Fable's network, research renderer | 13.8% | 15.5% |
| Fable's network, compiled and baked (this page) | 13.9% | 15.5% |
| Quantity | Value |
|---|---|
| Weights in the network | 2,957 |
| Weights that are not zero | 232 |
| Terms in the compiled shader | 116 |
| Density reads per ray-march step, before | 74 |
| Density reads per ray-march step, after baking | 15 |
| Frame rate while dragging the sun | 60 fps |
| Download | about 2.1 MB |
clouds/embed/ @ 1237ffe; network clouds/runs/r1/author/work/network.jsonFable worked for 1 hour 51 minutes and US$75.77 of model usage. The network it wrote has 41 probes and five small layers, 3,057 parameters in all. It is not a black box with physics-flavoured inputs. Fable's NETWORK.md writes the whole thing down as a handful of formulas, and every weight in the file is either a term in one of them or a constant it chose by reasoning:
- Direct sunlight is exact single scattering: the sun dimmed by the optical depth towards it (ten probes along the sun direction), times the phase function that says how much light turns towards the camera.
- Light that has only just entered gets a forward-scattering glow term. That is what makes the silver lining when the sun is behind the cloud.
- Deep, many-times-scattered light is modelled as a diffusion fluence that falls off with how buried the point is, measured with coarser probes towards the sun.
- Sky and ground light come from optical depths straight up and straight down, scaled by whether the point is on the top, a flank or the base.
The constants came from physics, from Fable's own Monte Carlo runs on slabs, spheres and a puck of the same medium, and from looking at its renders beside the references.
| Cloud-pixel luminance error | Reference (12 pairs) | Held back (6 pairs) |
|---|---|---|
| Single scattering only | 82.4% | 90.4% |
| Fable's network | 13.8% | 15.5% |
Single scattering is the obvious cheap baseline: light that bounces once. It gets the shape and the shadows but misses most of the light, which is why its error is so large. The network gets within about 14% on average on the views it could see, and about 15% on views it never saw. That is not film quality. The differences are visible side by side, mostly in how bright the deepest parts of the cloud are. But it is a long way from the baseline, and it came from a model reasoning about light transport, not fitting to images.
From a network to a shader
The research renderer evaluates the network as a generic interpreter: 41 probes per step, about 74 texture reads, hundreds of accumulated passes per image. It takes seconds a frame. Fine for scoring, useless in a blog post.
This is where a hand-written network pays off in a way a trained one usually doesn't. Its only 2,957 weights in total, and most layers pass values straight through. So I had Claude write a small compiler that treats the network as what it is, a program:
- Compile. Drop the zero weights, fold the constants, and emit straight-line GLSL. The result is 116 terms of shader arithmetic, and it matches the interpreter to float precision (the same 13.8% error, to four decimal places).
- Bake. Most of the probes do not depend on where the camera is. The ones in the world frame (up, down, local density) are baked into 3D textures once at load. The ones towards the sun are rebaked whenever the sun moves, which takes 1.5 to 4 ms on an M4 Pro. Only the two probes along the view ray stay live.
That takes each ray-march step from 74 texture reads to 15. Rendered this way, the cloud error is 13.9% on the reference split and 15.5% on the held-back split, scored once at the end, so the speed costs almost nothing in accuracy. On an M4 Pro it holds 60 fps while you drag the sun, dropping resolution during the drag and refining once you let go. The whole thing, three.js included, is about 2 MB.
None of that needed retraining or distillation. It needed the network to be legible enough that a compiler could see which parts depend on what. A trained network of the same size would have dense weights with no reason to separate "depends on the sun" from "depends on the view", and you'd get none of the baking for free.
What the Two Have in Common
The two jobs have nothing in common on the surface: one classifies agent logs, the other estimates light inside a cloud. But the way the networks were made, and what that makes them good for, is the same.
The expensive, stochastic step happens once. A frontier model reasons for an hour or two, under a harness that limits its tools, meters its cost and records every action. That is the part you'd want to govern, and it is easy to govern because it happens once, in a sandbox, with a cost cap.
What ships is small and deterministic. An 8.5 MB transformer that runs on a CPU, and a 3,057-parameter network that compiles to a shader. This means they are highly performant.
You can read them. Each comes with a document that names what every part computes, written by the author as it went. For the agent monitor that answers "why did it fire?". For the cloud it answers "why is the base too dark?".
They are made from a spec, not a dataset. The agent monitor started from zero labels and used 200. The cloud network never fitted anything. Where labels are expensive or the distribution keeps moving, that matters more than the last point of accuracy.
They are programs, so they compile. The cloud network became GLSL. The agent monitor could just as easily become a small model in a log pipeline, compiled into a WebAssembly module, or a rule engine.
When This Fits, and When It Doesn't
Both jobs had something in common that many jobs don't: the rule could be written down. Repetition of already-done work defines a stall. Light obeys radiative transfer. Fable's skill was in turning a rule into weights, and in choosing a good rule where the spec left room. Where nobody can say what the rule is (recognising faces, ranking search results, most of language), training on data might still be the route, and I have no evidence this approach competes there, but might make an interesting follow up experiment.
What This Opens Up
Step back from the two examples and the shape of the thing changes. Until now, getting a model of your own meant running a project: collect or generate a dataset, label it, pick an architecture, train it, evaluate it, and repeat when the data drifts. Most of the cost is in the data, and most jobs never justify it. So the usual answers have been a hand-written heuristic (cheap, brittle) or a call to a general-purpose LLM (flexible, but slow, paid for on every call and different every time).
Here, two hyper-specialised networks each came from a written spec, a harness that could check the output, and a few hours of a frontier model's time, for under US$80 each. No training run, no labelling pipeline, no GPU cluster. The agent monitor used 200 labelled windows for one revision; the cloud network used none, only reference images to look at. Some of what follows is shown by these two runs, and some is my extrapolation from them. I'll try to keep the two apart.
Affordable custom models for any organisation. When a bespoke model costs about as much as a day of engineering time, the long tail opens up: jobs that were always too small, too specific or too short-lived to justify an ML project or their application was in a business that didn't have the budget or technical maturity to do it. A detector for one customer's niche issues. A classifier for one internal workflow. A lighting model for one game's weather. My guess is that most of the useful models nobody has built are in that tail, not in another large general-purpose model.
Models that live in the repo. Both networks rebuild from a short script to the same bytes. That makes the spec, the builder and the design document the source, and the weights a build output. A change is a pull request someone can read, CI can rebuild the weights and check them, and rolling back is git revert. The rebuilds are shown here; running it that way across a team is not yet.
No LLM in the hot path. A lot of products now make an LLM call per event to classify, route or check something, because it was the only way to get judgement without a training project. A written network turns that into a fraction of a CPU-second per session. The frontier model does the hard thinking once, at authoring time, and the thing that runs on every event is small enough to put anywhere: in a log pipeline, in the agent harness, in a browser, in a shader, on a phone.
Labels become checks, not the source of the model Training needs labels in bulk; writing needed a few hundred to identify a mistake and correct a policy, and the cloud needed none at all. That changes the cold-start problem. A new product with no history, a new market, a new log format, a domain where the data is private and you'd rather not collect it: you can start from what you know, then use a small labelled set to check and revise. Data still matters. It just stops being the price of entry.
Expertise you can compile. Both networks encode knowledge the author could state: what makes a loop a loop, how light scatters. That suggests a different workflow, where the person who knows the domain (an SRE, a physicist, a fraud analyst) writes or reviews the spec, and the model turns it into weights. The design document that comes back is in their terms, so they can tell when it's wrong. Having worked across many domains in my career it makes me wonder where I could have applied this technique.
Adapting without retraining. When the agent monitor met logs from a different source, the fix was another authoring round: new labelled windows from that source, a recorded session, and a diff to the builder you can read. In the previous post that third round improved on four families of behaviour it had never seen (held-out OOD). Drift becomes a change you review, not a retrain you trust.
Graphics and simulation, not just classification. The cloud network suggests the same approach works wherever there's known physics to start from and a slow reference to check against: lighting, materials, fluid or cloth approximations, sensor models. A studio could have specialised neural components written for a scene and compiled to shaders, with no training pipeline at all. That is one run on one cloud, so treat it as a direction, not a result.
What doesn't go away is the work of saying what you want and checking you got it. Both runs depended on a precise spec and on a harness that could score the result: a simulator with sealed test sets for the agent monitor, path-traced references for the cloud. That is where the engineering effort moves, from collecting and labelling data to writing specs and building evaluations. For a lot of teams, that is work they already know how to do.
Methods. Weight author for both networks: Fable (claude-fable-5-1), in isolated, audited Claude Code sessions with no fitting tools. Agent monitor: the v0.3 written network (Phase B), scored once on sealed test and sealed OOD; OOD generator written by Codex. Cloud network: one run, 1 h 51 min of sessions, US$75.77 of model usage (API-equivalent) including a US$10 aborted first attempt; references path-traced in Mitsuba 3; cloud error is the mean relative luminance error over cloud pixels (clouds/scripts/score.py), on 12 reference and 6 held-back sun and camera pairs. The compiler and the live page were written by Claude and checked against the research renderer on the reference split; the held-back split was scored once at the end.